Search an ambiguous brand name through two routes: distinctive identifiers on their own, and the common name paired with product context. Add exclusions only after checking which relevant posts they would remove. Keep a broader review query beside the reporting query so you can find missed mentions as well as irrelevant matches.
A brand social listening query needs a written definition of relevance. For example: include public discussion of the brand's products, buying experience and comparisons; exclude ordinary uses of its name. Decide separately whether your own posts belong in the report. These are editorial choices for your project, not platform rules.
Build two routes into the query
The first route contains identifiers that strongly suggest the brand: its full trading name, product names, account mentions or a distinctive campaign hashtag. Check that each identifier belongs to the brand before treating it as reliable.
The second route contains the ambiguous word plus context. A fictional luggage brand called Harbor might need suitcase, luggage, carry-on or a model name near its name. A harbor weather report should not qualify merely because it contains Harbor.
Use this conceptual structure, then translate it into your tool's supported syntax:
DISTINCTIVE IDENTIFIERS
OR
(AMBIGUOUS NAME AND PRODUCT CONTEXT AND NOT REVIEWED EXCLUSIONS)
Keep exclusions inside the ambiguous-name route when possible. A travel post can name a luggage brand and discuss a cruise port in the same sentence. A global exclusion for port could discard it even when the full brand name is present.
Sprout Social's query guide describes additions and exclusions as ongoing maintenance. Its broader point applies here: review the words people use and revise the query when the results change. The worksheet below adds a separate record of what each revision loses.
A worksheet for three ambiguous names
All brands, product names, spelling variants and post fragments below are fictional exercises. Any resemblance to an existing business is incidental. The variants are candidates for testing, not evidence of how real customers spell anything.
| Fictional brand | Distinctive route | Common-name route | Exclusion to test | Relevant mention at risk |
|---|---|---|---|---|
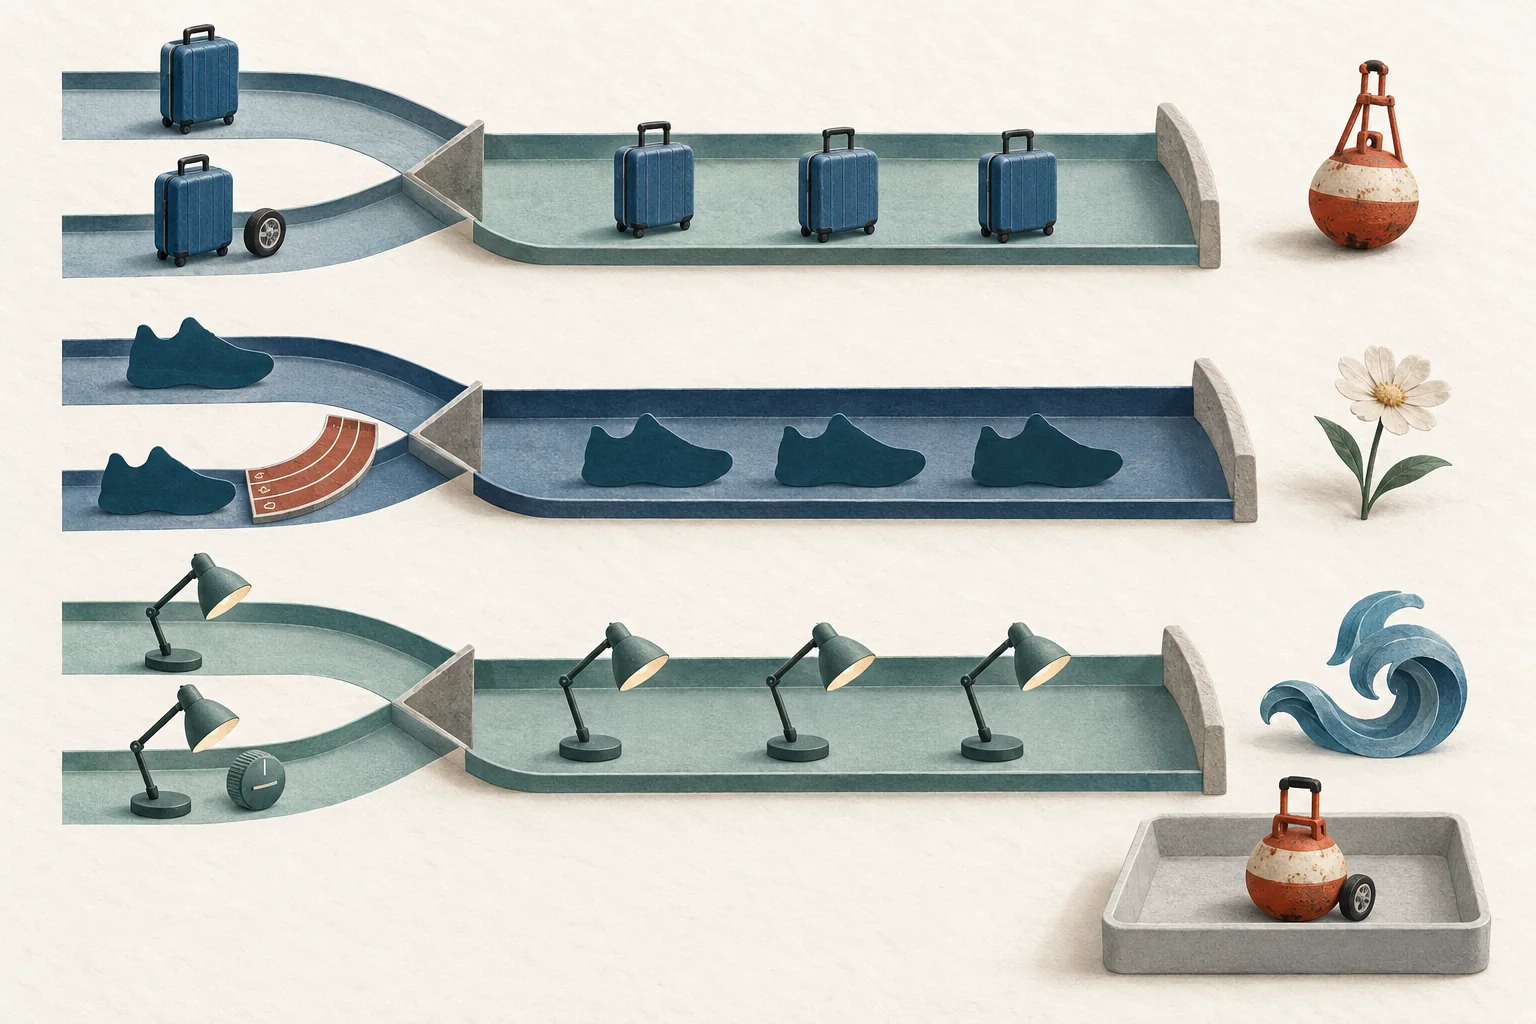
| Harbor, luggage | Harbor Luggage; Harbor Cabin 28 | Harbor or Harbour, with luggage, suitcase or carry-on | harbor master | A customer collecting a suitcase from a harbor master's office |
| Bloom, running shoes | Bloom Stride; Bloom footwear | Bloom or Blom, with running, sneaker or shoe | algae bloom | A runner discussing shoes worn beside a lake with an algae bloom |
| Current, desk lamps | Current desk lamp; Current Arc Mini | Current or Curent, with lamp, lighting or dimmer | ocean current | A buyer describing an ocean-current-inspired room and its new lamp |
For each row, write down the decision behind every term:
- Identifier: Why does this term point to this brand? Could another business or ordinary phrase use it?
- Context: Does this word appear in customer language, or only in the product catalog?
- Exclusion: Which reviewed irrelevant posts would it remove? Which relevant posts could it also remove?
- Variant: Where did the spelling come from? Keep unobserved variants in a test query until they earn a place.
Product context also creates misses. A post saying "Harbor arrived broken" would fail the common-name route if it lacked luggage vocabulary. If the surrounding thread confirms the brand, record it as a missed relevant item. Do not force the reviewer to call it irrelevant because the query missed it.
For a larger variant inventory, use the nickname, misspelling and transliteration workflow. Add terms with a reason, rather than generating every possible typo.
Translate the worksheet into platform syntax
Boolean syntax varies. In X API search queries, a space means AND, uppercase OR joins alternatives, and a minus sign excludes a term. Parentheses group conditions. X says to negate individual operators rather than negate a grouped expression.
Here is a proposed X API search expression for the fictional Harbor example. It illustrates documented syntax; it has not been run against live posts:
("Harbor Luggage" OR "Harbor Cabin 28") OR ((Harbor OR Harbour) (luggage OR suitcase OR "carry-on") -"harbor master")The full-name route can still match a post containing harbor master. The ambiguous route cannot. Test this distinction in your tool before adopting the exclusion.
Capitalization will not disambiguate Harbor in X API search: its operators are case-insensitive. X also documents differences between search and filtered stream. Search matches a quote post's own content rather than the original post it quotes. A relevant quotation can therefore be absent because the searchable text lacks the brand, even when a reader sees it in context.
Record the retrieval boundary beside the query. X's search documentation lists keywords, hashtags, mentions and URLs as searchable signals. Recent search covers the last seven days. Full-archive access is available to pay-per-use and Enterprise customers. API use requires an approved developer account, a Project and App, and the app's keys and tokens.
Those rules describe X API search. They do not establish what another network or a listening vendor can retrieve. Check the tool's supported sources, time window and fields before blaming an empty result on your keywords. Keep unavailable content separate from content your query filtered out.
Review both false positives and false negatives
Save a version of the query before editing. For each candidate change, compare the same source, language and time window. Keep a review sheet with these columns:
| Field | What to record |
|---|---|
| Item | Post URL or retained item ID, timestamp and source |
| Relevance | Relevant, irrelevant or unresolved, with a short reason |
| Match | Whether each query version retrieved it |
| Error cause | Ordinary-word use, unrelated business, missing context, spelling or exclusion |
| Decision | Keep the term, change it, or retain manual review |
Build the review set through more than one route. Include results from the proposed query, a broader name query, and known relevant posts found through verified identifiers. Review items removed by an exclusion. Freeze the set before comparing versions so the denominator does not change halfway through the test.
Ask another reviewer to check unresolved items and disagreements against the written relevance rule. Keep unresolved items visible and report how many you excluded from the calculation. This is a recommended working procedure, not a platform requirement.
The information retrieval textbook hosted by Stanford defines precision as the share of retrieved items that are relevant. Recall is the share of relevant items retrieved. You need known relevant items outside the query's results to examine its misses.
The following numbers are hypothetical and refer to one fixed, fully labeled review set containing 30 relevant posts:
| Query version | Relevant retrieved | Irrelevant retrieved | Relevant missed | Precision | Recall within this set |
|---|---|---|---|---|---|
| Name with context | 24 | 16 | 6 | 24 / 40 = 60% | 24 / 30 = 80% |
| After an exclusion | 21 | 4 | 9 | 21 / 25 = 84% | 21 / 30 = 70% |
The exclusion removed 12 irrelevant posts and three relevant posts. Decide whether that loss fits the task. For complaint detection, those three misses may justify keeping a broader manual-review queue. For a tightly scoped product report, a narrower query may be acceptable if you disclose the rule.
These results describe the review set. A convenience sample cannot establish how often the wider public mentions the brand, and this test cannot measure recall across unseen content. If duplicates dominate the sample, deduplicate the listening set before comparing versions.
Keep the decision with the query
Store the query text, version date, source coverage, review counts and reason for each exclusion together. Keep negative words such as broken, late and refund unless the project has a stated reason to exclude them. Removing criticism would change which experiences the report can show.
Choose one ambiguous name from your own brief. Fill its worksheet row, label a fixed review set, then test one exclusion at a time. Before promoting the revised query, inspect every known relevant item it loses. Use a declared source set when reporting share of voice so the eventual metric retains the boundaries you tested.